Showing posts with label Text. Show all posts

Wednesday, May 8, 2013

Modeling Blobs for a Data Warehouse and Concatenating Nvarchar(max), Varchar(max), TEXT, NTEXT in a SSIS Scripting Component

     When dealing with facts and dimensions in a data warehouse, you usually model for attributes of the event such as employee involved, day it occurred, customer associated, etc. (dimensions). These are then associated with measures to quantify the event such as minutes to completion, cost, quantity used, etc. (facts). This scenario is easy, lots of documentation out there. What's troubling is when we introduce a blob to this scenario. If you deal with data in any kind of service related field, or medical field, you are bound to have to load and report on large text fields for these repair notes or doctor's notes. 

     When attempting to model this scenario, you really only have 4 options.
  • Create a fact-less fact 
    • Have the blob contained in a column in the fact and have dimensions hang off of it such as employee dimension (who created the note) day dimension (when was it created) and customer dimension (customer who was serviced) as well as a degenerate dimension for a transaction number and note identifier(or creation date if a combination of transaction number and creation date creates a unique identifier for a compound key)
    • Every record will correspond to an individual note entered into the source system
    • Easy to load and, if you're using SQL Server, will be stored separately from the other data in the table. So queries that don't involve the blob will not affect query performance
Figure 1. Fact-less Fact Solution
  • Create a bridge table 
    • Move the notes to a separate dimension, will have to also move creation time and employee information(since the employee that may be associated with the fact record may not be the same employee that wrote the note)
    • create a "bridge" between the transaction fact and the notes dimension with an ordering column to sort by
    • Can work with facts that contain multiple records for same transaction
    • Hard to load and maintain, not easy for end users to understand

Figure 2. Bridge Table Solution
  • Concatenate notes for transaction and place in column in fact
    • Will only be viable if the transaction can be expressed in a single row in the fact, else you will have to concatenate and copy for each row associated with that transaction....yuck.
    • Creation Date and Employee information will have to be concatenated with the note and notes will have to be separated by some kind of line break
    • Breaks some design paradigms (See rule #7) 

Figure 3. Note Concatenated in Fact Solution 

  • Concatenate notes for transaction in a single dimension
    • Can work with facts that contain multiple records for same transaction
    • Creation Date and Employee information will have to be concatenated with the note and notes will have to be separated by some kind of line break
    • This means that your dimension will grow at the same rate as your transaction growth, this can get ugly 
Figure 4. Note Concatenated in Dimension Solution
     The first solution is by far the easiest to deal with from an ETL stand point. The second  is definitely the hardest of the 4 solutions to implement. The last 2 are very similar in that both need to have the notes concatenated in association with the transaction. The next section will demonstrate how to prep the data for either solution 3 or solution 4 using a script component in SSIS.  

Sample Data Set:
Figure 5. Sample Data Set

     The sample data set we're going to use for this will consist of a transaction identifier (TRANS_NO nvarchar(10)), a note creation date (CREATE_DATE datetime), and a note written about the transaction (SERVICE_NOTE nvarchar(max)). This will be the data in the OLE DB Source. The goal is to take the notes and create dates of these 2 transactions and concatenate them into one note, the result being 2 records (1 for each transaction). It is very important that this data set is sorted. The transaction numbers need to be grouped together as shown in this example or the following script component won't work.

Example Data Flow:
Figure 6. Example Data Flow
(Ignore the Union All transformation, I have that here so that I can later add a data viewer to the data stream. You would usually have your data destinations here instead)

     First thing is to configure the amount of rows we want to go through the scripting component at a time. I find that 1000 seems to be good for my projects, anything more than that I see sporadic performance. You may experience differences in your project. In the design surface of your data flow, right click and select properties. Then go to the DefaultBufferMaxRows and type 1000 for the value:

Figure 7. DefaultBufferMaxRows Setting


Creating the Script Component:
     Drag a scripting component onto the data flow design surface from the tool box. Connect the output of the OLE DB source to the script component. Now lets configure. Open the script component. Leave everything on the script screen at its default:


Figure 8. Script Screen

     On the input screen select the 3 columns from our OLE DB Source:

Figure 9. Input Columns Screen

     On the Inputs and Outputs screen expand Output0 and click on Output Folders node. We're going to add 2 columns to this output by clicking the Add Column button. One column we'll name TRANSNOOUT and make it a Unicode string [DT_WSTR] with a length of 10. The second column we'll name NOTE_OUT and make it a Unicode text stream [DT_NTEXT]:

Figure 10. Adding Columns to Output

Before we leave this screen we have one more important thing to do. Click on the Output0 node. In common properties section we need to change the SynchronousInputID selection to none: 

Figure 11. Changing the SynchronousInputID Value

According to Microsoft's description (see previous link) "For a synchronous output, where rows are passed through to the selected output or outputs without adding any new rows, this property should contain the ID of the component's input." Since we are going to replace the rows going in with new concatenated rows, we need to select None.
Since we're not using any Connection Managers lets go back to the Script screen, click the Edit Script button and paste the following code:

using System;
using System.Collections;
using System.Collections.Generic;
using System.Data;
using System.Diagnostics;
using System.Windows.Forms;
using Microsoft.SqlServer.Dts.Pipeline.Wrapper;
using Microsoft.SqlServer.Dts.Runtime.Wrapper;
using System.Text;


[Microsoft.SqlServer.Dts.Pipeline.SSISScriptComponentEntryPointAttribute()]

public class ScriptMain : UserComponent
{
    //Holds current transaction number in buffer
    private string transNo;

    //String builders that concatenates the notes
    StringBuilder concatNote = new StringBuilder();

    //Boolean for determining if loop is on first row of series or not
    private bool firstRow = true;


    public override void Input0_ProcessInputRow(Input0Buffer Row)
    {
        //Converts our note from the input buffer to string
        int noteLen = Convert.ToInt32(Row.SERVICENOTE.Length);
        byte[] noteBlob = new byte[noteLen];
        noteBlob = Row.SERVICENOTE.GetBlobData(0, noteLen);
        string ServiceStr = System.Text.Encoding.Unicode.GetString(noteBlob);
        //Holds the create date from the input buffer
        string createDate = Row.CREATEDATE.ToString();

        //If were still within the same transaction(will be false for first row coming in the input buffer)
        if (Row.TRANSNO == transNo)
        {
            //Pass notes to the concat function
            concatNote.Append(createDate+ "\r\n"+ServiceStr + "\r\n");
        }
        else
        {
            //If this is the first record in a new series we dont want to add a record to the output yet
            if (firstRow)
            {
            //We set the indicator to false now so that when we compare transaction numbers again, and were
            //not on the same transaction, we need to output a record
                firstRow = false;
            }
            else
            {
          
                // If the transaction number has changed we output the string for the current transaction no
                //Add a row to the output buffer
                Output0Buffer.AddRow();
                //Pass through the transaction number
                Output0Buffer.TRANSNOOUT = transNo;
                //Output the concatenated note
                Output0Buffer.NOTEOUT.AddBlobData(Encoding.Unicode.GetBytes(concatNote.ToString()));
        
                //Reset the string builder for the next transaction(done in .net 2.0, so no .Clear() method
                concatNote.Length = 0;
                concatNote.Capacity = 0;

            }
            //Prep for next transaction
            transNo = Row.TRANSNO;
            concatNote.Append(createDate + "\r\n" + ServiceStr + "\r\n");
        }
    }

    public override void Input0_ProcessInput(Input0Buffer Buffer)
    {
        base.Input0_ProcessInput(Buffer);

        //Makes sure last record in buffer gets outputted
            if (Buffer.EndOfRowset())
            {
                Output0Buffer.AddRow();
                Output0Buffer.TRANSNOOUT = transNo;
                Output0Buffer.NOTEOUT.AddBlobData(Encoding.Unicode.GetBytes(concatNote.ToString()));
                Output0Buffer.SetEndOfRowset();
            }
       

    }

}


     Lets step through and explain some of this code. if (Row.TRANSNO == transNo)determines if the transaction number were dealing with is the same as the previous one in the buffer. This way we know if we need to still keep concatenating notes or not. You'll notice when setting the note blob to a string the encoding is Unicode string ServiceStr = System.Text.Encoding.Unicode.GetString(noteBlob);. This is because the blob coming through the input buffer is an nvarchar(max). If you were using a TEXT or varchar(max) column the encoding should be changed to ASCII as: string ServiceStr = System.Text.Encoding.ASCII.GetString(noteBlob);.  Output0Buffer.AddRow(); is where we add a new record to our output buffer and output the concatenated note with the transaction number:

Figure 12. Data Viewer

As you can see the original 8 records have been condensed to 2 with notes concatenated in the NOTE_OUT field. Since the data viewer cant display blobs I created a message box (MessageBox.Show("Transaction Number: " + transNo + "\r\n" + "Note: "+concatNote.ToString());) that will display the data for us:


Figure 13. Result for Transaction 1122424566

Figure 14. Result for Transaction 1122580388
Now we're ready to either add this to a fact table or slap surrogate keys on them and insert them into a dimension.


Tuesday, May 7, 2013

Creating a Script Component in SSIS that can Generate a Hash Value for a Row

    Generating hash values for your data can be extremely useful in data warehousing. It is an excellent way to tell if the data coming through staging, from your source systems, has changed or not. This is accomplished by pushing individual rows of data through some type of hashing algorithm and adding the output as a value on your data stream. When that particular row comes through staging again you can compare the hash value generating in staging to the hash stored with your data in the data warehouse. This enables you to determine if a change has occurred  in the row, and if your data warehouse row needs to be updated(or if you need to insert a new record if you are change tracking).

     Without utilizing something like a hash, you will have to compare every column in your incoming data stream to its associated column in your data warehouse in something like a conditional split transformation with a syntax like (COLUMN_A_NEW != COLUMN_A_DW) || (COLUMN_B_NEW != COLUMN_B_DW) ...etc. For records with many columns, this can be a daunting task. This will also have to be custom to every package you have as data sources for each package will be different. This provides little to no re-usability and is very inflexible to change. Thus, we use a hash.

     I've seen a couple of ways this has been done in different systems, some good....some not so good. One way, if your source system developers have blessed you with this feature, is to simply get a hash value for your record from the source system. You can store this hash value with the data and do a simple comparison in your conditional split transformation, HASH_VALUE_SOURCE != HASH_VALUE_DW. If they are different we process the update, if not we do nothing.  Another way I've seen is with creating a custom scripting component that maps out each individual column coming through and generating a hash. While this is still better than doing this in a conditional split transformation, its still too customized to the package and inflexible to change. Thus every time you add/remove a column to the transformation, the code in the scripting component needs to be updated. There is no re-usability.  A third way I've seen is simply to not use a hash at all. Just use some kind of add/change dating mechanism from the source, to determine what records to stage, and blindly update the data warehouse, whether records have changed or not. Now this is not very efficient at all is it?

     The best way, in my opinion, is to create a scripting component that is flexible to change, reusable, ASCII/Unicode capable and the ability to customize features (to a certain degree). I'll take you step by step through a simple implementation of this:

     First here is what our sample package looks like (in the data flow tab):


Figure 1. Data Flow 
Our OLE DB Source contains 2 columns, a transaction identifier,varchar(50), and a note associated with the transaction ,varchar(max), (this can also be a TEXT or NTEXT or nvarchar(max) depending on your particular needs).


Figure 2. OLE-DB Data Source
         Some of your projects may need to develop hash values that are dependent on case sensitive or case-insensitive data, i.e. "this is a test = This is a Test" or "this is a test != This is a Test". For that let's create a variable that our scripting component can later use to determine case sensitivity (by the way, when dealing with variables in SSIS I find bids helper invaluable). In this example I'll make it case sensitive by defaulting my string variable to Y.


Figure 3. Variable for Case Sensitivity

  In the tool box drag a Script Component onto the data flow designer surface. You will first be asked to a choose a scripting component type:


Figure 4  Script Component Type Selection
      Select transformation, as we want data to pass through and not be a source or destination for it. In this example I named this component "
Script Component - Populate Hash Value Field with BLOBS". Now open the component. The default screen you should see is:
Figure 5. Scripting Component
     Leave the ScriptLanguage to the default of C# because Visual Basic is.......yuck. Now we want our scripting component to make use of the case sensitive variable we created, so we need to add this to our list of ReadOnlyVariables this scripting component can use.


Figure 6. Select Case Sensitive Variable


     Now that we selected our variable, lets select our input columns. 


Figure 7. Input Columns
In our data flow we should have 3 columns, RMA_ITEM_ID, ITEM_COMMENT and LAST_MOD_DATE_df. Since LAST_MOD_DATE_df is different every time we run the package, we don't want this value considered when generating the hash value. If we did the hash would be different every time and would defeat the purpose of tracking changes to our row. Keep this in mind when we create our scripting component.

     Now that we selected the inputs for our scripting component, we need to create an output column for the hash value we want the scripting component to generate. Click on Inputs and Outputs in the menu. In that screen expand Output 0 and click on Output Columns. Then click on the Add Column button and create a new output column for our hash value. 


Figure 8. Output Columns
     We're not using any Connection Managers for this example, so lets jump back to the script menu and click the Edit Script button. Here is where we want to code our method for creating a hash, see code below:

#region Help:  Introduction to the Script Component
/* The Script Component allows you to perform virtually any operation that can be accomplished in
 * a .Net application within the context of an Integration Services data flow.
 *
 * Expand the other regions which have "Help" prefixes for examples of specific ways to use
 * Integration Services features within this script component. */
#endregion

#region Namespaces
using System;
using System.Collections;
using System.Collections.Generic;
using System.Data;
using System.Diagnostics;
using Microsoft.SqlServer.Dts.Pipeline.Wrapper;
using Microsoft.SqlServer.Dts.Runtime.Wrapper;
using Microsoft.SqlServer.Dts.Pipeline;
using System.Text;
using System.Windows.Forms;
using System.Security.Cryptography;
using Microsoft.SqlServer.Dts.Runtime;
#endregion

#region Class
/// <summary>
/// This is the class to which to add your code.  Do not change the name, attributes, or parent
/// of this class.
/// </summary>
[Microsoft.SqlServer.Dts.Pipeline.SSISScriptComponentEntryPointAttribute()]
public class ScriptMain : UserComponent
{

#region Methods
    private PipelineBuffer inputBuffer;

    /// <summary>
    /// The ProcessInput method is called to provide the component a full PipelineBuffer object that contains rows from the upstream component.
    /// The columns contained in buffer include those columns defined in the IDTSInputColumnCollection100 of the component.
    /// If the component has synchronous outputs, the buffer will also include the columns added to the output column collection by the component,
    /// and all the columns in the output column collection of the components upstream from the component.
    /// </summary>
    /// <param name="InputID">The ID of the input of the component.</param>
    /// <param name="Buffer">The PipelineBuffer object.</param>
    public override void ProcessInput(int InputID, Microsoft.SqlServer.Dts.Pipeline.PipelineBuffer Buffer)
    {
        inputBuffer = Buffer;
        base.ProcessInput(InputID, Buffer);
    }
    /// <summary>
    /// This method is called once for every row that passes through the component from Input0.
    ///
    /// Example of reading a value from a column in the the row:
    ///  string zipCode = Row.ZipCode
    ///
    /// Example of writing a value to a column in the row:
    ///  Row.ZipCode = zipCode
    /// </summary>
    /// <param name="Row">The row that is currently passing through the component</param>
    public override void Input0_ProcessInputRow(Input0Buffer Row)
    {
        //Holds the number of columns in the row
        int counter = 0;
        //Used to concatenate columns in our row
        StringBuilder values = new StringBuilder();
        //Will be used to hold the value of the column in the loop
        object value = null;
        //Will be used to capture the string
        string probStr = null;
        //Will be used to hold the length of the blob
        int probBlobLen = 0;
        //Will be used to hold the bytes of the blob
        byte[] probbytBlob = null;
        //Will be used to test the type of blob(ASCII or Unicode)
        object tester = null;
        //Will be used to determine case sensitivity
        string caseSensitive = Variables.strCaseSensitive;

        //Loops through the columns in the current record in the buffer
        for (counter = 0; counter < inputBuffer.ColumnCount - 1; counter++)
        {
            //Checks for null values in the column, if not we process the value, else we submit a blank to the string builder
            if (inputBuffer.IsNull(counter) == false)
            {
                //Sets tester to the object type of the column being evaluated in the loop
                tester = inputBuffer[counter].GetType();
                //Gets SSIS specific data type
                BufferColumn bc = inputBuffer.GetColumnInfo(counter);

                //Checks to see if the data is a BLOB
                if (object.ReferenceEquals(tester, typeof(BlobColumn)))
                {

                    //Convert BLOB data to string
                    probBlobLen = (int)inputBuffer.GetBlobLength(counter);
                    probbytBlob = inputBuffer.GetBlobData(counter, 0, probBlobLen);

                    //If input is Unicode
                    if (bc.DataType == DataType.DT_NTEXT)
                    {
                        probStr = System.Text.Encoding.Unicode.GetString(probbytBlob);

                    }
                    //If input is ASCII
                    else
                    {
                        probStr = System.Text.Encoding.ASCII.GetString(probbytBlob);

                    }
                    //Sets the value object to the current column in the loop if BLOB
                    value = probStr;
                }
                else
                {
                    //Sets the value object to the current column in the loop
                    value = inputBuffer[counter].ToString();

                }
                //Appends the StringBuilder with the value from the current column in the loop
                values.Append(value);
            }
            else
            {
                //Appends the String Builder with a blank if the incoming column has a null value
                values.Append("");
            }
        }

        //Sets the output of the component to the SHA1 hash of the String Builder value

        //Not case sensitve
        if (caseSensitive == "N")
        {
            Row.HASHVALUE = CreateHash(values.ToString().ToUpper());
        }
        //Case sensitive
        else
        {
            Row.HASHVALUE = CreateHash(values.ToString());

        }

    }

    /// <summary>
    /// Generates a SHA1 hash value for a string passed
    /// </summary>
    /// <param name="data">Data string that is to be hashed</param>
    /// <returns>SAH1 hash value string</returns>
    public static string CreateHash(string data)
    {
        byte[] dataToHash = (new UnicodeEncoding()).GetBytes(data);
        SHA1CryptoServiceProvider sha = new SHA1CryptoServiceProvider();
        byte[] hashedData = sha.ComputeHash(dataToHash);
        RNGCryptoServiceProvider.Create().GetBytes(dataToHash);
        string s = Convert.ToBase64String(hashedData, Base64FormattingOptions.None);
        return s;
    }
#endregion
}
#endregion

     Lets step through and explain some of this code. First thing you're going to want to do is override the Input0_ProcessInputRow method. Here is where we are going to customize what happens on our data flow. Our main for-loop will loop through the columns of our row in the input buffer. In our loop we want to concatenate the values in our columns into a StringBuilder object. This means converting every value that comes through the loop to a string (this means Blobs as well if (object.ReferenceEquals(tester, typeof(BlobColumn)))).  

     When attempting to convert a Blob to a string encoding is an important factor, thus we want to test the encoding of the Blob so we know which type to use when converting to string if (bc.DataType == DataType.DT_NTEXT). Once we've added our column values to the StringBuilder, we need to generate our hash value for the record and bind that value to the HASH_VALUE output we defined. We do this by calling CreateHash and deciding whether or not our hash should be case sensitive  Row.HASHVALUE = CreateHash(values.ToString()); or case insensitive  Row.HASHVALUE = CreateHash(values.ToString().ToUpper());. The CreateHash method takes a string parameter runs its through a SHA1 hash and returns our hash value. 

     By putting a data viewer on the data flow you can now see this column added:


Figure 9. Data Viewer


Unfortunately, the data viewer only displays Blobs as <Long Text>. Here is a message box (MessageBox.Show("Concatenated String: " + values.ToString() +"\r\n" + "Hash Value: " + CreateHash(values.ToString()));) to show how this will ultimately look:

Figure 10. Sample Output

    We have now successfully added our hash value to our data stream. We then pass this data through a look-up to determine if the natural key already exists in our destination or not. In this transformation we want to add the hash value for this record that already exists in our warehouse:

Figure 11. Adding the existing hash value to the data stream


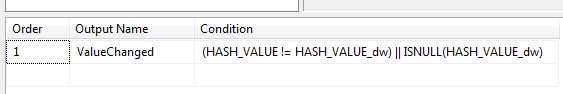
 If it already exists we need to send the data through a conditional split transformation to determine if a change has occurred:

Figure 12.  Comparing new hash with existing hash

     If the 2 values are different we know the data has changed and we can move the data off somewhere to stage it for updating the destination. If the values are the same we do nothing.

     With this solution we achieve:
  •  flexible to change (you can add more columns or remove them by simply checking/unchecking them on the script menu in the scripting component)
  • reusable (You can add this as a custom component to your project or simply copy and paste it from one package to another)
  • ASCII/Unicode capable (No matter what kind of data you throw at it ASCII/Unicode, Blob, string, int, date time, etc. you will be able to generate a hash)
  • ability to customize features (Making it case sensitive/case insensitive via passing variables. This can be further customized to add more variables that will change behavior and accommodate your specific project)